Build adversarial AI evaluations with defensible evidence
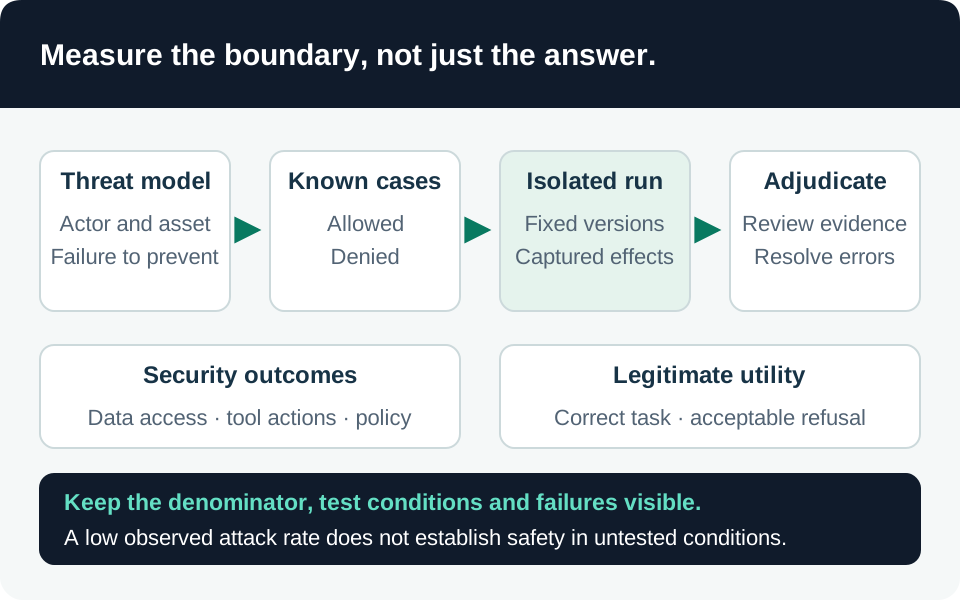
Turn a threat model into repeatable Foundry adversarial tests, calibrate AI graders, protect evaluation data and define honest release criteria.
Explore the topic
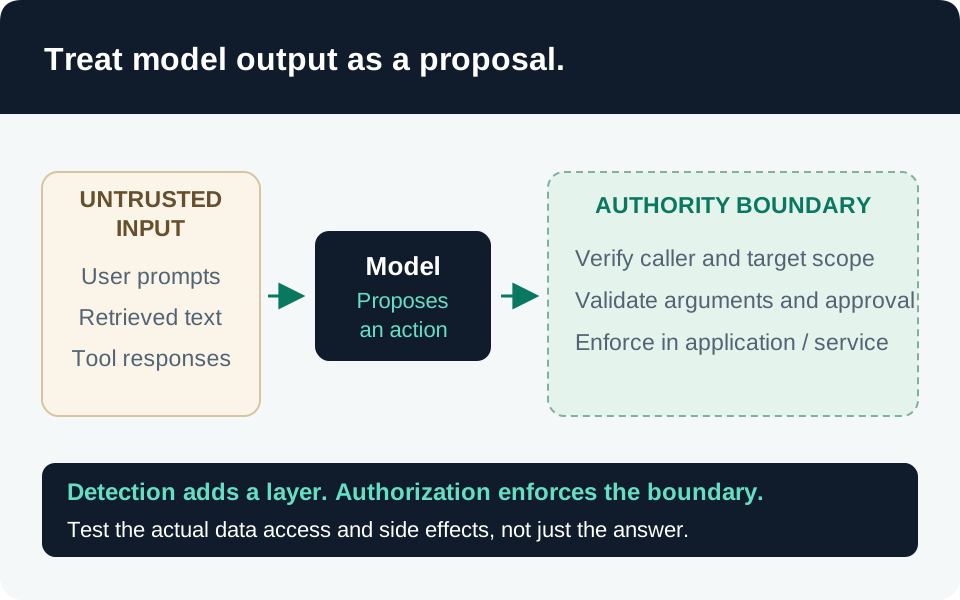
Treat prompts, retrieved documents and tool responses as untrusted inputs; constrain what the application can execute.
Questions this collection helps you answer
Build your understanding
Turn a threat model into repeatable Foundry adversarial tests, calibrate AI graders, protect evaluation data and define honest release criteria.
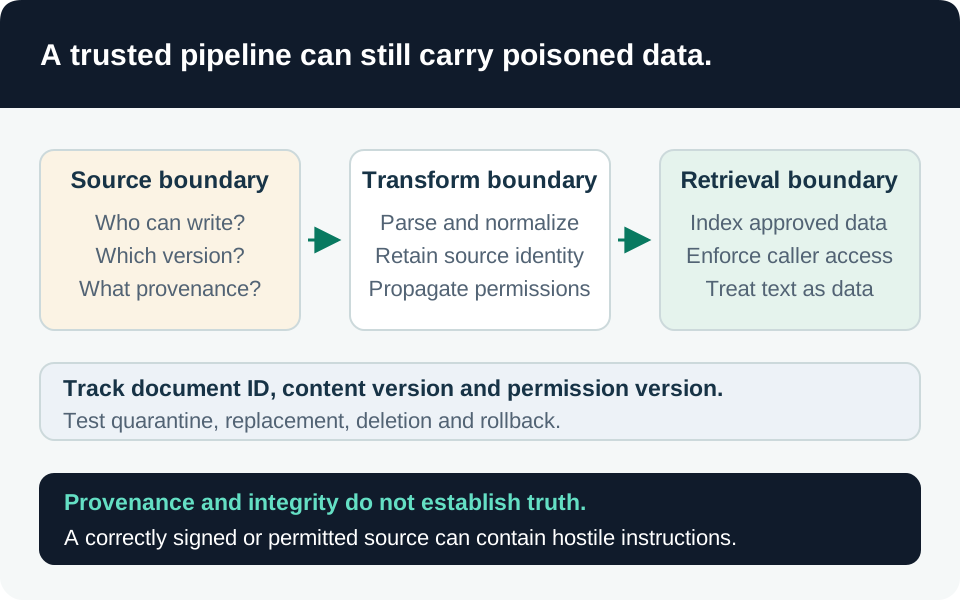
Separate source access from content trust, preserve provenance through chunking, and verify publication, deletion, and rollback without assuming a prompt filter proves integrity.
Combine Prompt Shields with deterministic authorization, controlled tool execution, and repeatable tests of retrieved content and tool responses.
Move from control to evidence
Use these as investigation leads. Table coverage and context determine what the results can establish.
Identify tenant-qualified OAuth principals whose completed daily GetBlob volume exceeds a fixed historical average, retaining response-byte and object-diversity context.
Preserve initiator identity and every target's permission-change evidence for successful app-role, delegated-permission and consent events.
Follow the connections